DEVELOPER NOTES
An AI coding eval should catch the bug, not admire the answer
Build a compact evaluation set with hidden cases, independent checks, and honest first-attempt results.
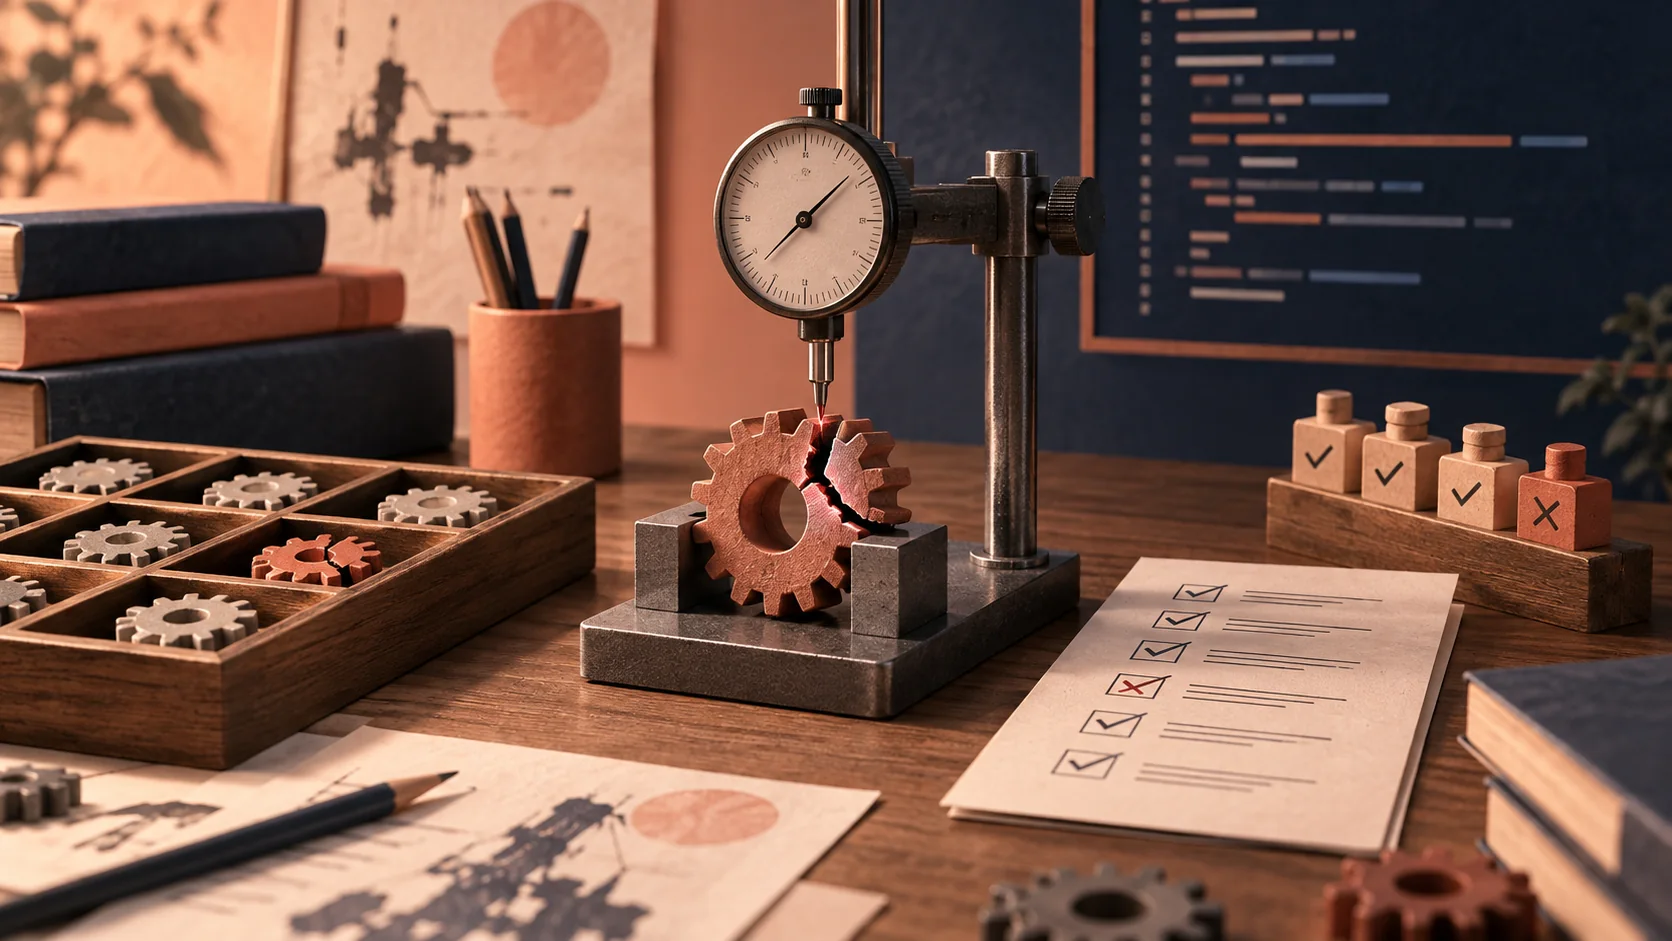
A persuasive explanation can make a wrong patch feel finished. That is why I prefer coding evaluations where the application gets a vote. The agent can explain its reasoning, but the changed behavior needs independent evidence. This is a practical evaluation recipe, not a leaderboard or a claim about one model's performance.
Start from failures you care about
Pick several small tasks that represent actual work: an import boundary, a permission check, a timezone conversion, a missing empty state, and an expensive query. Store a sanitized fixture and expected behavior for each. Include a task where the correct response is to explain insufficient information rather than invent a fix.
Before running an agent, verify that the target failure exists. A regression test that already passes cannot prove the proposed change repaired it. Keep some checks hidden from the prompt so the worker cannot merely imitate the visible assertion. Hidden does not mean unfair: the expected behavior should follow from the stated requirement.
Freeze the evaluation contract
Record repository revision, environment, task text, model configuration, allowed tools, and timeout. Keep the test harness outside the files the worker may casually edit. If the task explicitly requires changing tests, retain an independent acceptance check as well. Otherwise deleting the failing assertion can become an accidental “success.”
Score dimensions separately: required behavior, unrelated regressions, permission boundaries, patch scope, and evidence quality. A single number can conceal a serious issue. A correct output obtained by exposing a secret is not an acceptable pass.
Count attempts honestly
Measure first-attempt success separately from success after feedback. Include all retries and reviewer repair in time and cost. If a human supplies the missing algorithm, record that assistance. It is still useful to know that a model becomes productive with guidance; it is misleading to call the result fully independent.
Repeat cases where nondeterminism matters and retain failures. Review false failures too: a flaky test or environment outage should not be silently counted as a reasoning defect. Categorize it and report the denominator you actually measured.
Turn a failure into a better fixture
After a real escape, add the smallest reproduction that would have caught it. Keep the set compact enough to run before changes to the model, harness, or dependency environment. Rotate some held-out cases so optimization does not collapse into memorizing one suite.
The best eval report lets another developer inspect a failing input, the patch, and the check. A nice explanation is welcome. A repeatable behavioral result is what tells us whether the assistant is making the engineering work better.
AIコード評価は説明より不具合を確かめる
説得力のある説明でも、修正が正しいとは限らない。AIのコード評価では、実際の動作に発言権を持たせたい。これはモデル順位ではなく、小さな評価セットの作り方だ。
現実の失敗を選ぶ
入力境界、権限、時差、空状態、遅い問い合わせなどの小さな課題を選ぶ。匿名化した入力と期待動作を用意し、情報不足を認めるべき課題も入れる。修正前に失敗することを確認する。最初から成功するテストでは修理を証明できない。
要求から分かる公平な確認を一部非公開にする。基点コミット、環境、依頼、モデル、ツール、時間上限を固定する。評価側の検査を自由に変更できる場所に置かない。テスト変更が課題でも独立した受け入れ検査を残す。
成功を分けて数える
必要動作、無関係な回帰、権限、差分範囲、証拠を別々に採点する。秘密を漏らして正解しても合格ではない。初回成功と助言後成功を分け、再試行と人の修正の費用を含める。環境停止や不安定なテストは別に分類し、実際の試行数を示す。
逃した不具合から最小再現を追加し、モデルや実行環境を変える前に回せる大きさを保つ。一部の未使用ケースを更新し、固定問題の暗記だけにならないようにする。説明だけでなく、入力・差分・検査を他人が追える報告を目指そう。
Put this idea into practice
Keep reading
A September vision fix is a reminder to keep your image test set
Test OCR and image reasoning with preserved inputs, expected outcomes, and separate model-versus-preprocessing checks.
Give your AI-built app a small recovery drill
Test a harmless failure in staging, capture the recovery timeline, and turn the result into a runbook someone else can follow.
Give your coding agent a task contract it can finish
Specify the target, boundaries, evidence, and handoff before a small task grows into an unreviewable rewrite.